Foundations · reviewed · reviewed Sep 1, 2026 · 3 min
What is a perceptron?
A perceptron multiplies input features by learned weights, adds a bias, and applies a threshold to choose between two classes. Its update rule can find a separating boundary when one exists, but one perceptron cannot represent a problem that is not linearly separable.
One weighted decision
Suppose an input is represented by features x₁, x₂, …, xₙ. A
perceptron gives each feature a weight, adds a bias, and calculates a score:
score = w₁x₁ + w₂x₂ + … + wₙxₙ + b
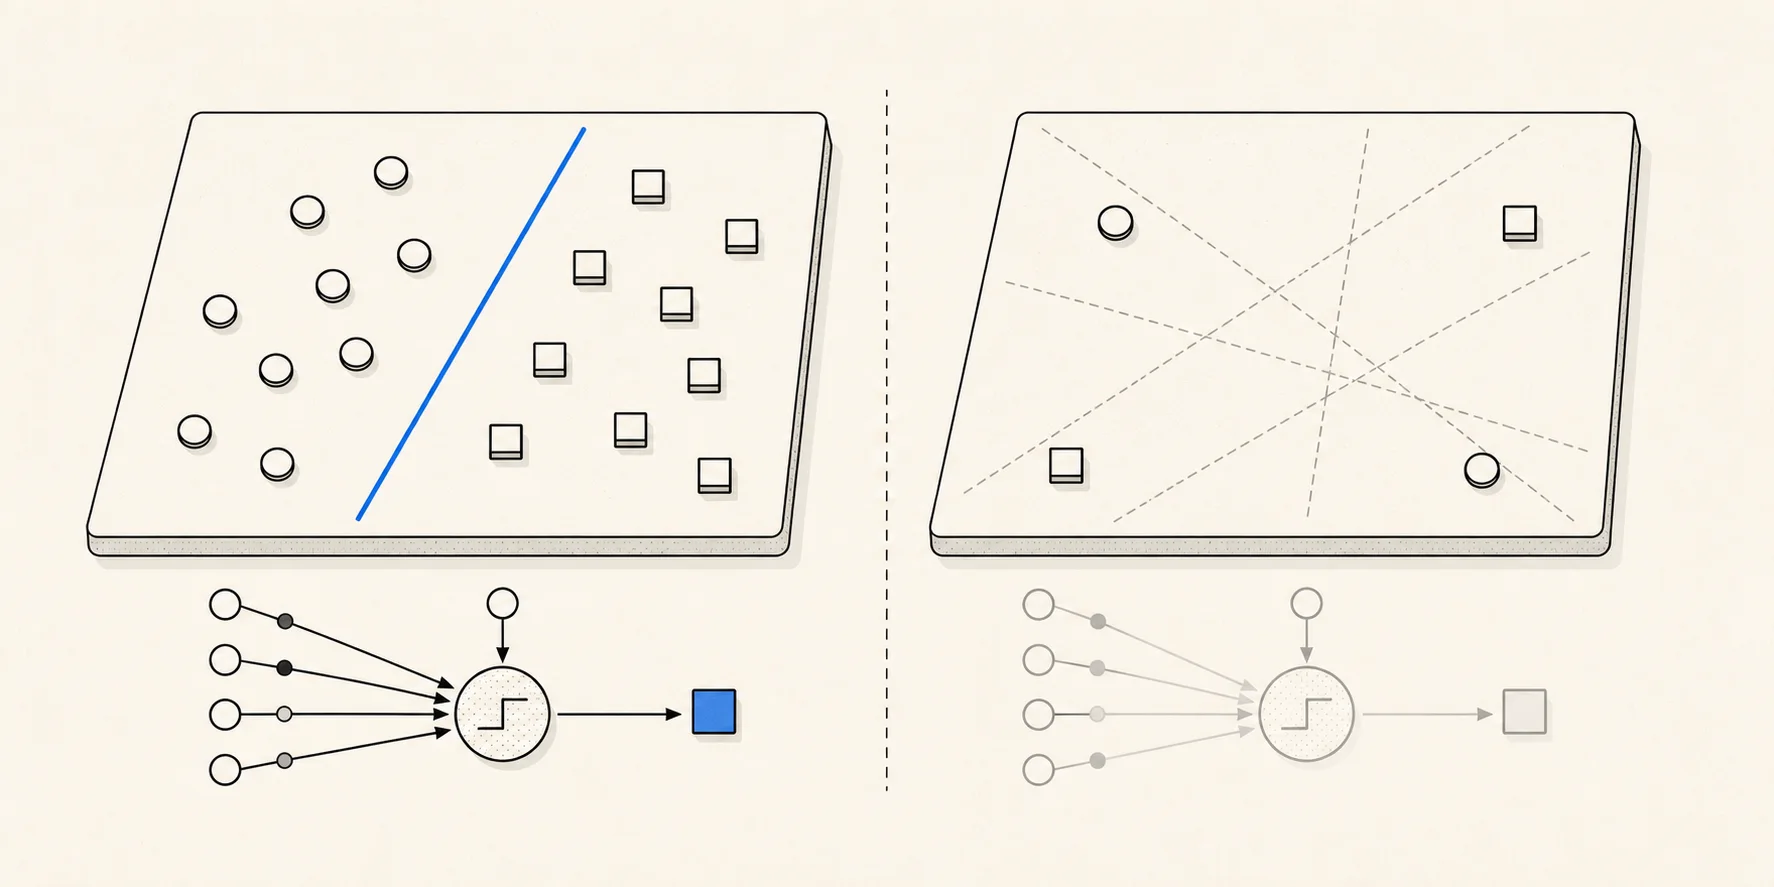
The same linear-threshold mechanism explains both panels: it can learn the blue separator when one straight boundary exists, but no single straight line separates opposite-corner XOR classes.
The sign of that score selects one of two classes. A positive weight makes its feature push the decision toward one class; a negative weight pushes toward the other. The bias moves the threshold without changing the feature values.
Geometrically, the weights and bias define a line in two dimensions, a plane in three, or a hyperplane in more dimensions. The output says which side contains the input. Calling the perceptron a “neuron” is a mathematical and historical analogy, not a claim that it reproduces a biological neuron.
Move the line, keep the four inputs
Use two binary inputs, x₁ and x₂. For OR, the positive class contains every point except (0, 0). Fixed weights 1, 1 and bias −0.5 separate it: the scores are −0.5, 0.5, 0.5, 1.5.
For XOR, only (0, 1) and (1, 0) are positive. The input coordinates stay identical; the required labels change. Predict what moving one straight boundary can fix—and which point will become wrong elsewhere.
Adjust the weights and bias below, then switch from OR to XOR. The classifications and mistake count are calculated locally from the four visible points.
Explore the mechanism
Move one decision boundary
Filled points require class 1; outlined points require class 0. The line marks score = 0. Inspect the predicted class in the table.
- Correct points
- 4 / 4
| Input | Score | Predicted | Required |
|---|---|---|---|
| 0, 0 | -0.5 | 0 | 0 |
| 0, 1 | 0.5 | 1 | 1 |
| 1, 0 | 0.5 | 1 | 1 |
| 1, 1 | 1.5 | 1 | 1 |
Computed scores for four binary inputs with hand-chosen weights. No optimizer or real model runs. A score of zero belongs to class 1.
A remaining XOR error is not evidence that the learning rate needs more tuning. One affine threshold cannot express this label pattern. The next article adds a nonlinear hidden representation rather than asking the same line to do more work.
Learning by correcting mistakes
Training presents labelled examples one at a time. If the perceptron predicts an example correctly, its weights can remain unchanged. If it predicts the wrong class, the update shifts the weights toward the correct label. Repeated mistakes therefore rotate and move the boundary.
For linearly separable training data, the classic convergence result says this procedure will eventually find a separating boundary under its assumptions. It does not promise the unique or best boundary, calibrated probabilities, or good performance on unseen data. Feature scale, ordering, margin, noise, and the relationship between training and production data still matter.
The XOR limit
Some class patterns cannot be divided by one straight boundary. XOR is the compact example: opposite corners of a square share a label, so every line that separates one pair splits the other pair incorrectly. A single perceptron cannot solve it regardless of how long it is trained.
That failure is architectural, not merely an optimizer problem. Combining units in layers and inserting nonlinear activation functions lets a network build intermediate representations whose final classes can be separated. This is the bridge from one linear threshold to a multilayer neural network.
Why engineers still learn it
Modern language models are vastly larger and use different components, losses, and training systems, but the perceptron exposes enduring ideas in a small form: numeric features, parameters, a forward calculation, a decision boundary, an update driven by error, and a capacity limit imposed by architecture.
It also prevents a common misconception. A learned model is not intelligent because a unit resembles a neuron or because training found weights. What it can represent follows from the complete architecture and data; what a deployed AI system can do also depends on the software around the model.
Sources
Sources and further reading
- 01The Perceptron: A Probabilistic Model for Information Storage and Organization in the BrainFrank Rosenblatt · research · published Nov 1, 1958 · source checked Sep 1, 2026
The original perceptron paper, used for the historical mechanism and the distinction between the mathematical model and a biological claim.
- 02On Convergence Proofs for PerceptronsAlbert B. Novikoff · research · source checked Sep 1, 2026
The classic concise convergence proof, grounding the bounded claim that mistake-driven updates succeed when a linear separator exists.
- 03Deep LearningGoodfellow, Bengio, and Courville · guide · published Nov 18, 2016 · source checked Aug 30, 2026
Foundational reference for optimization, backpropagation, generalization, and deep neural networks.